active project
SignalForge
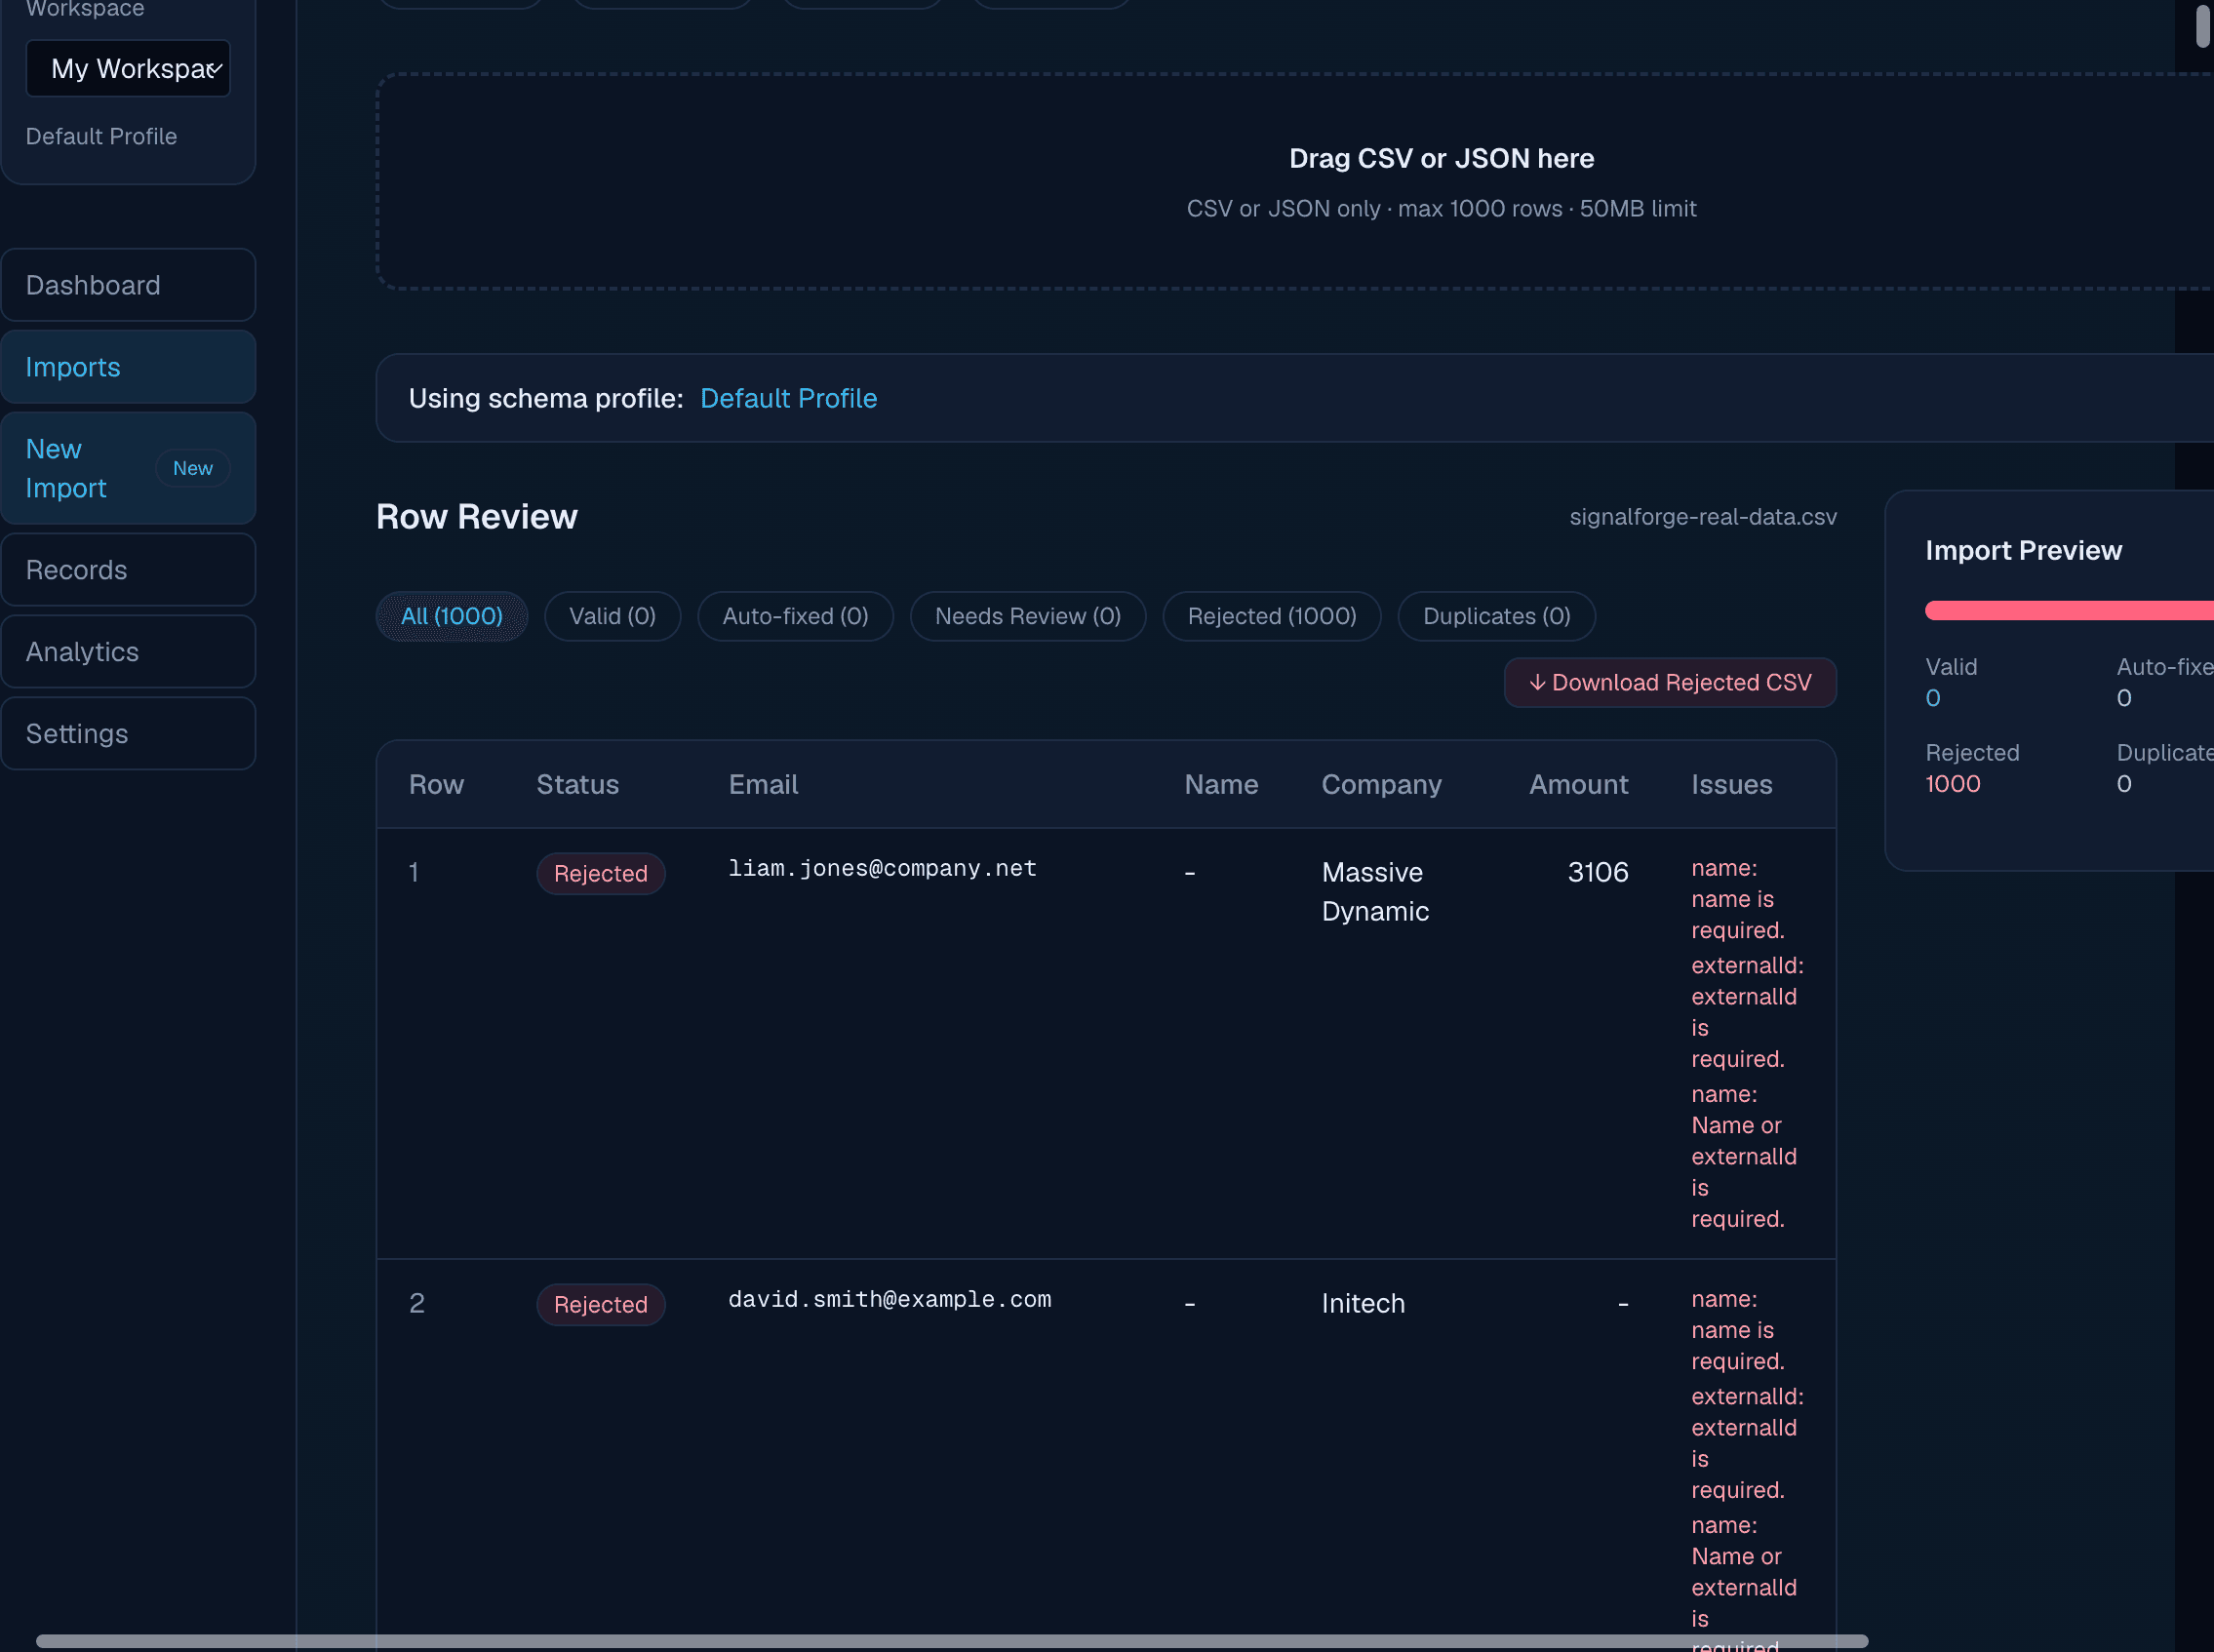
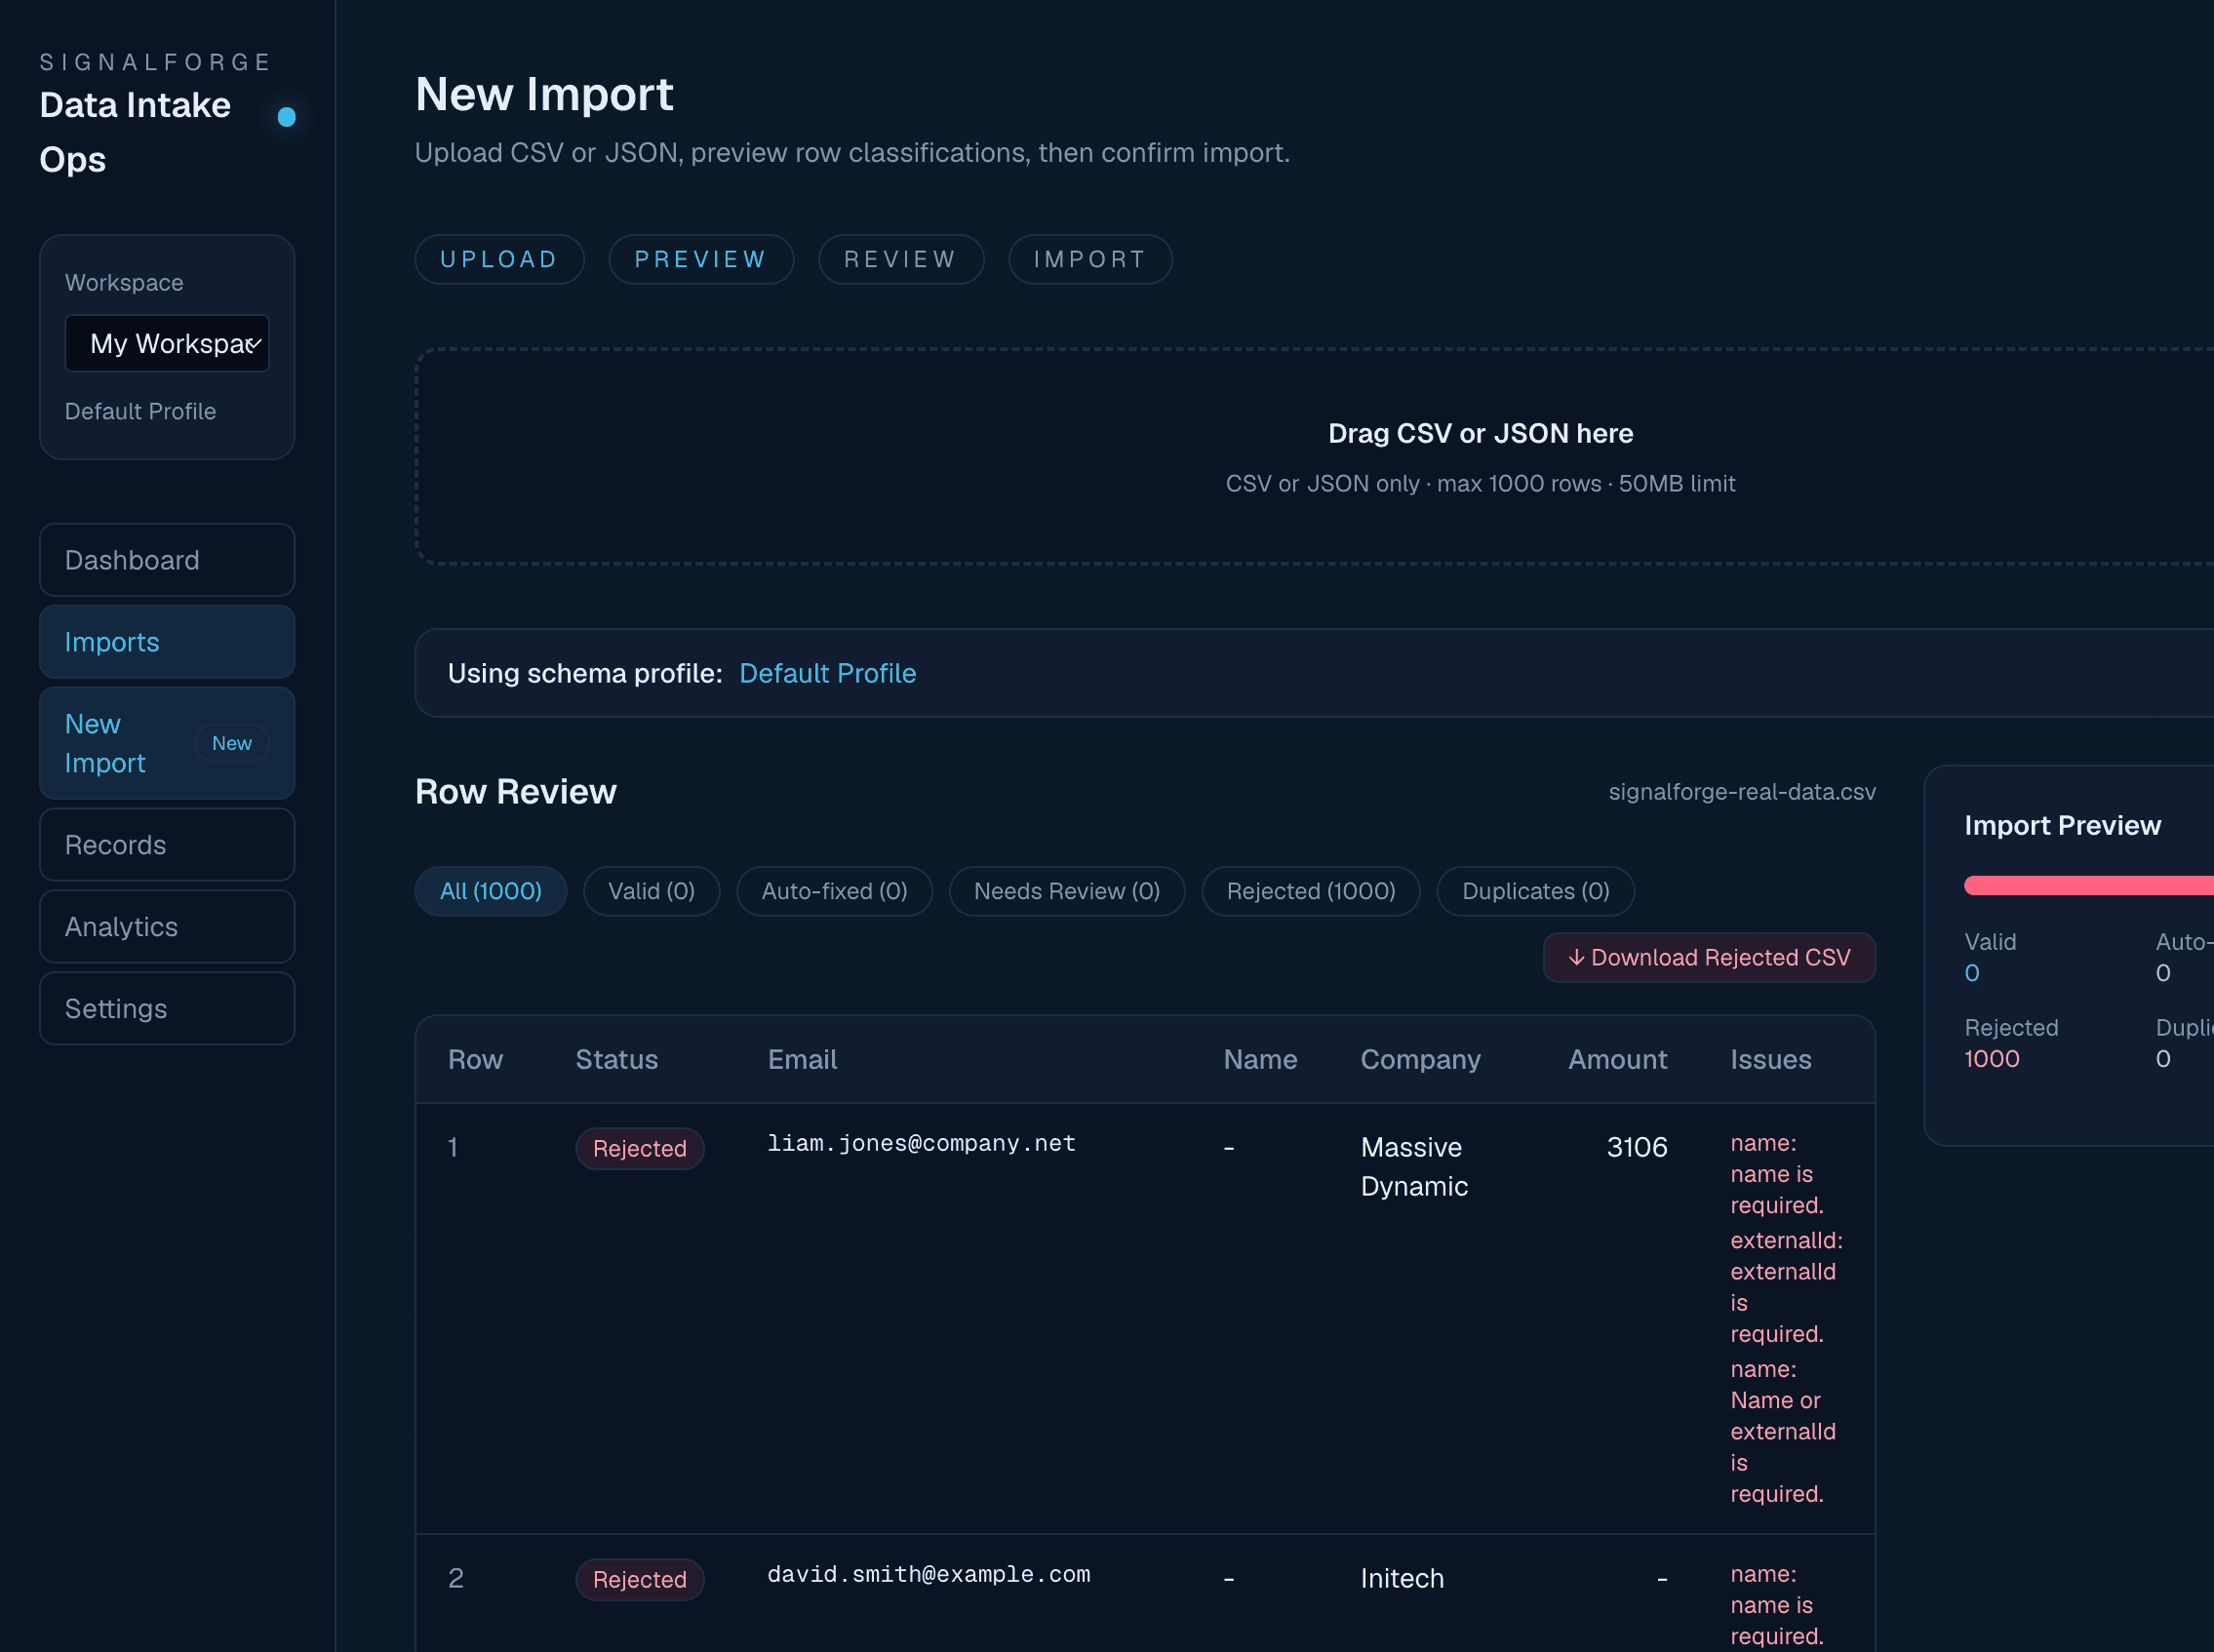
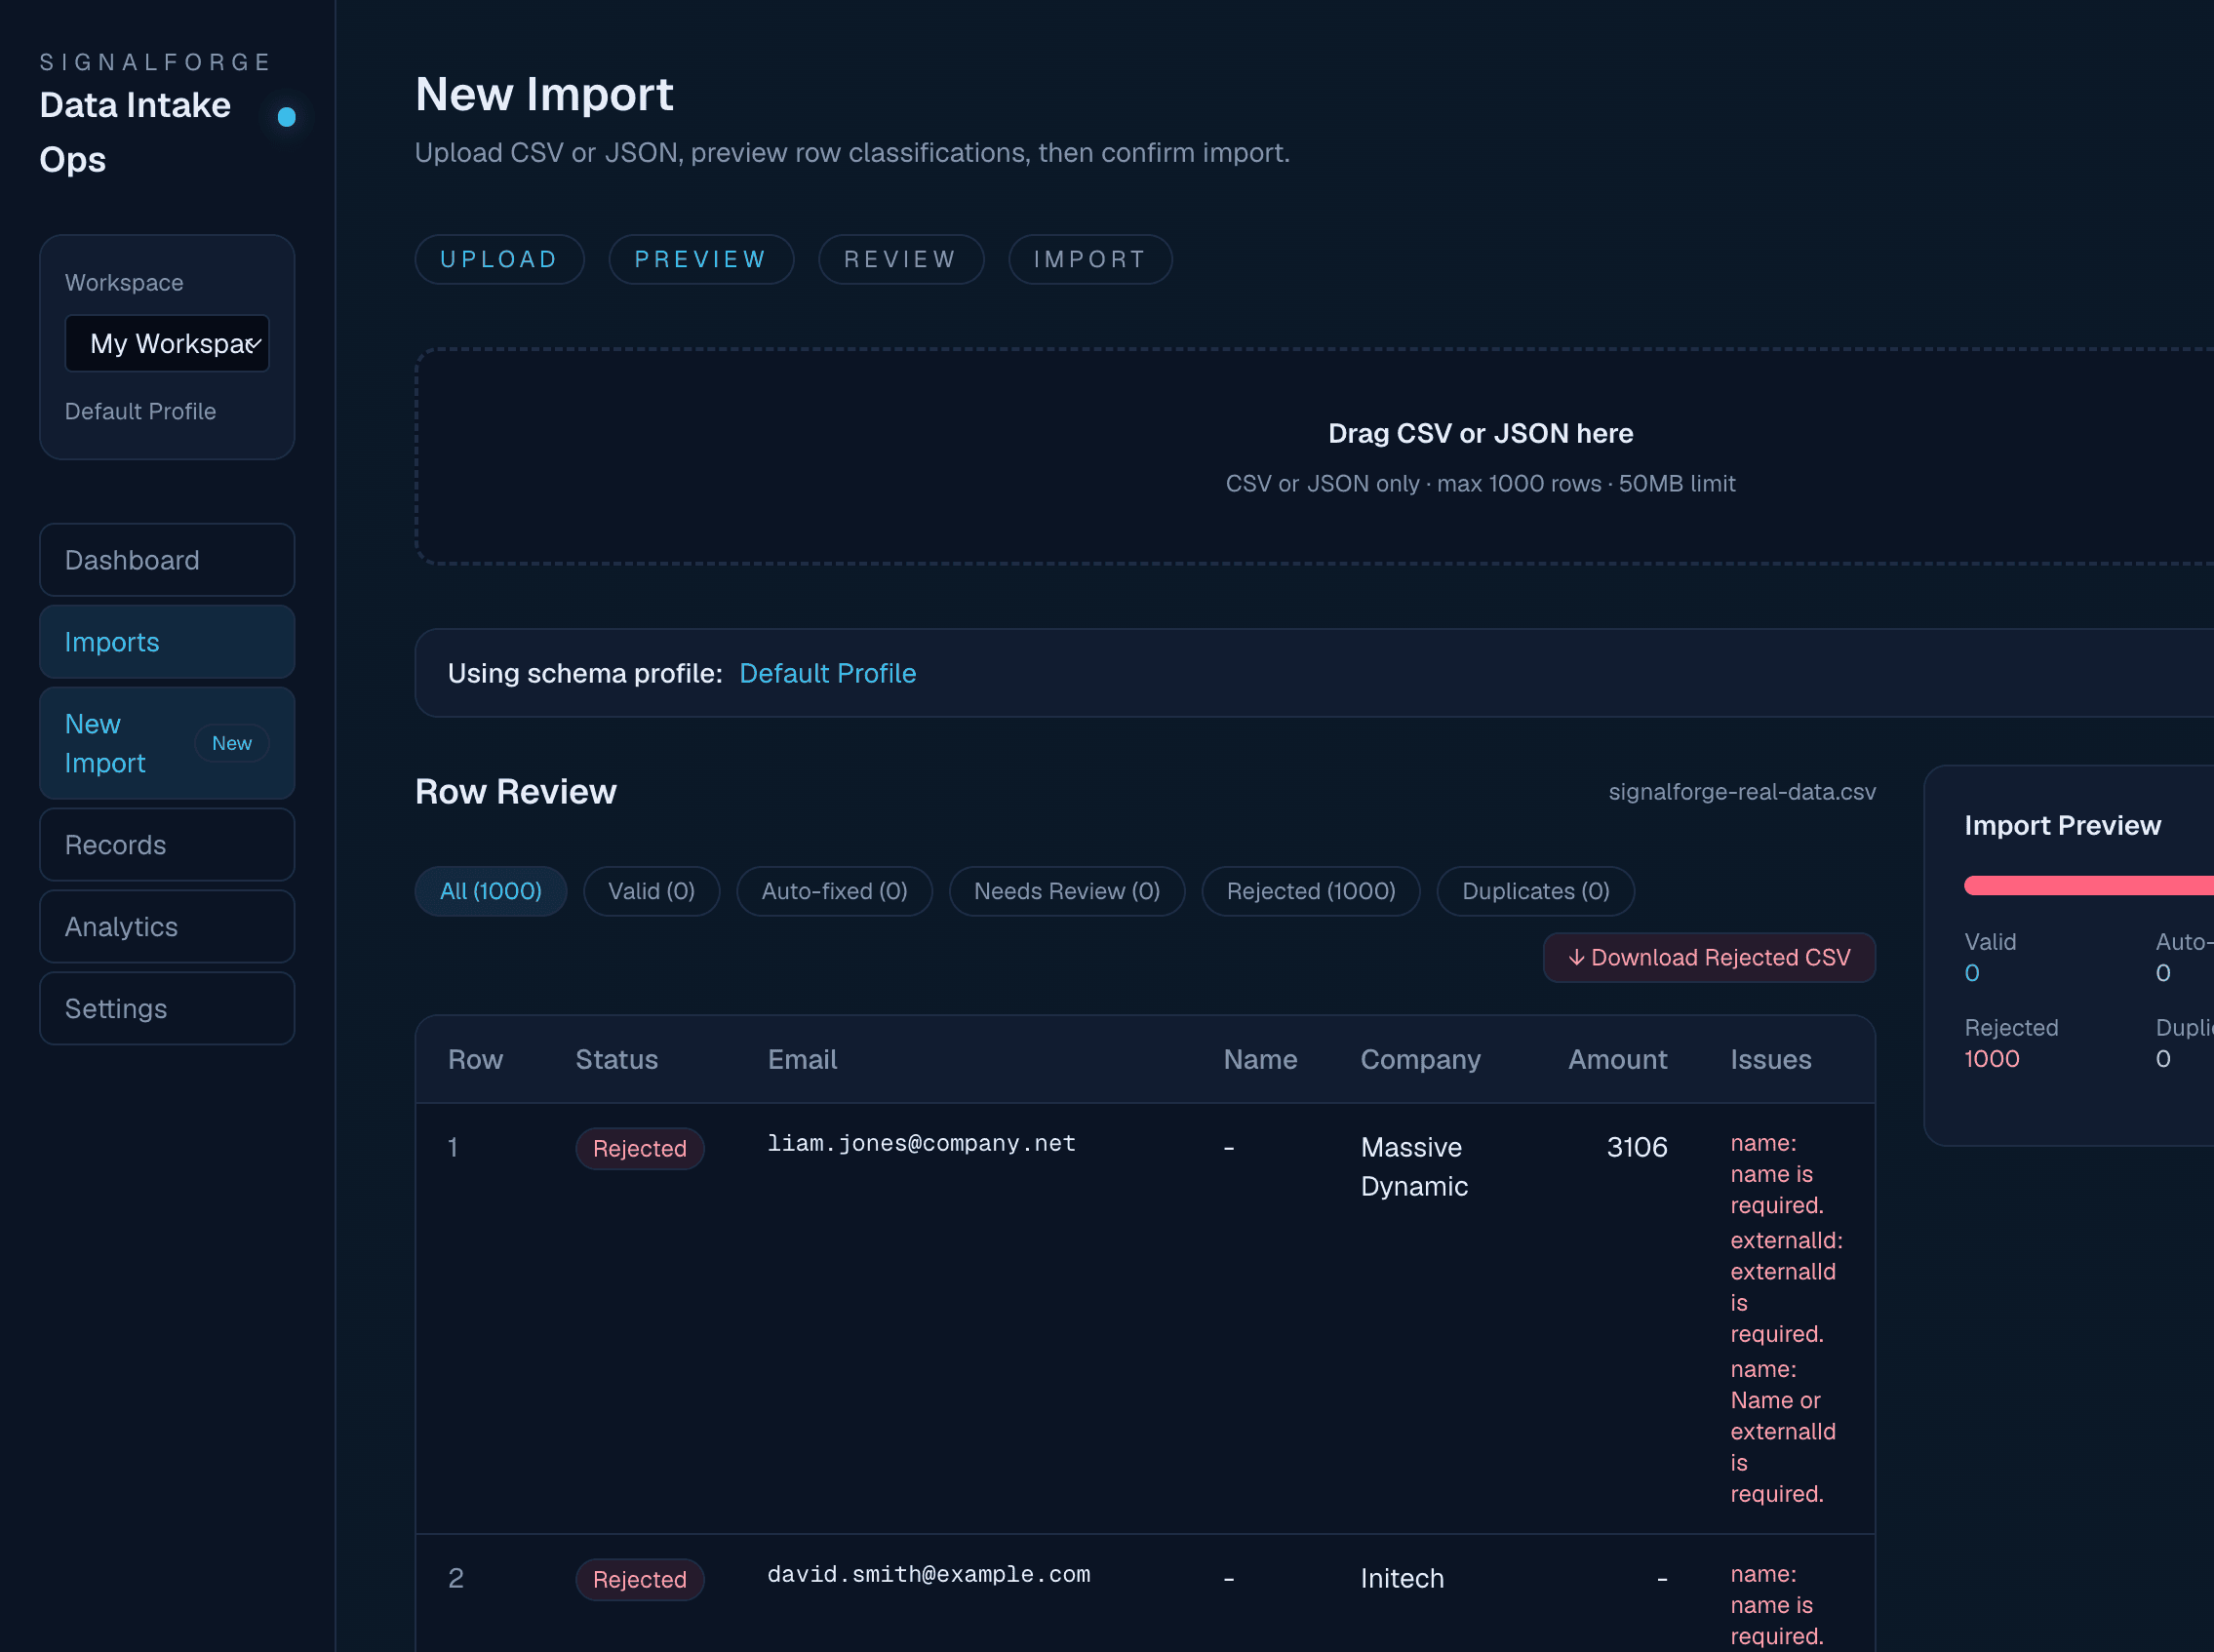
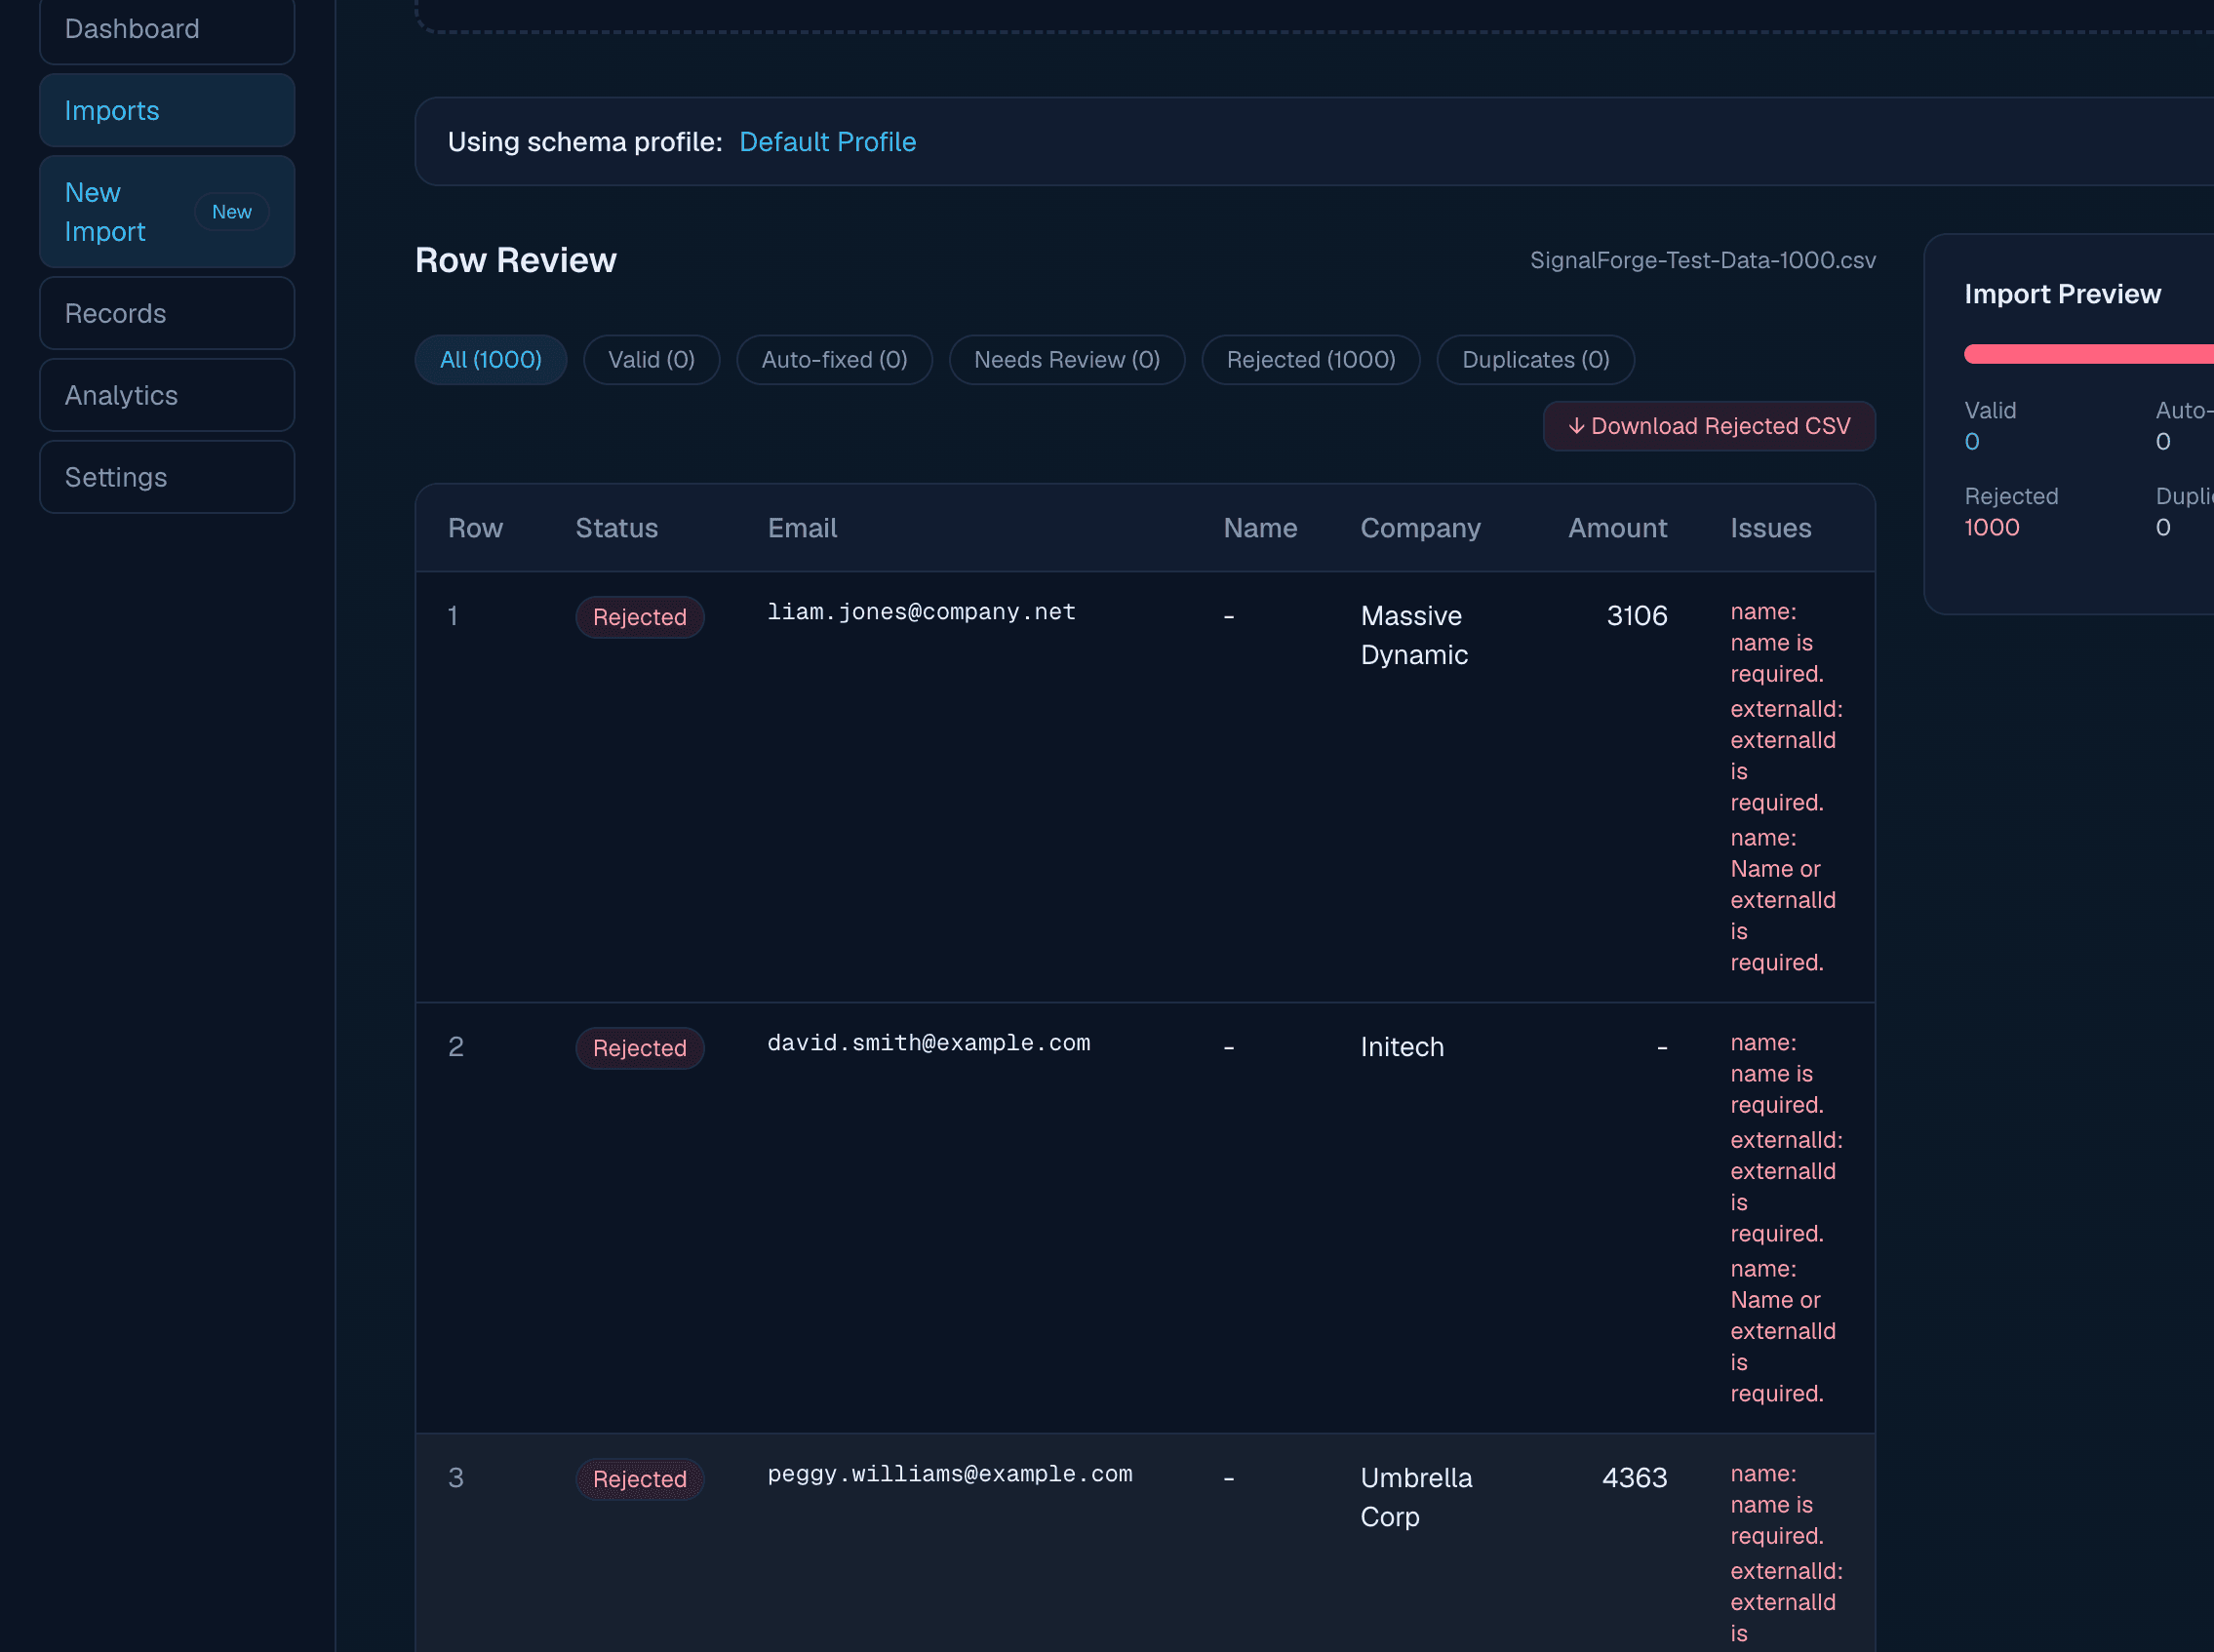
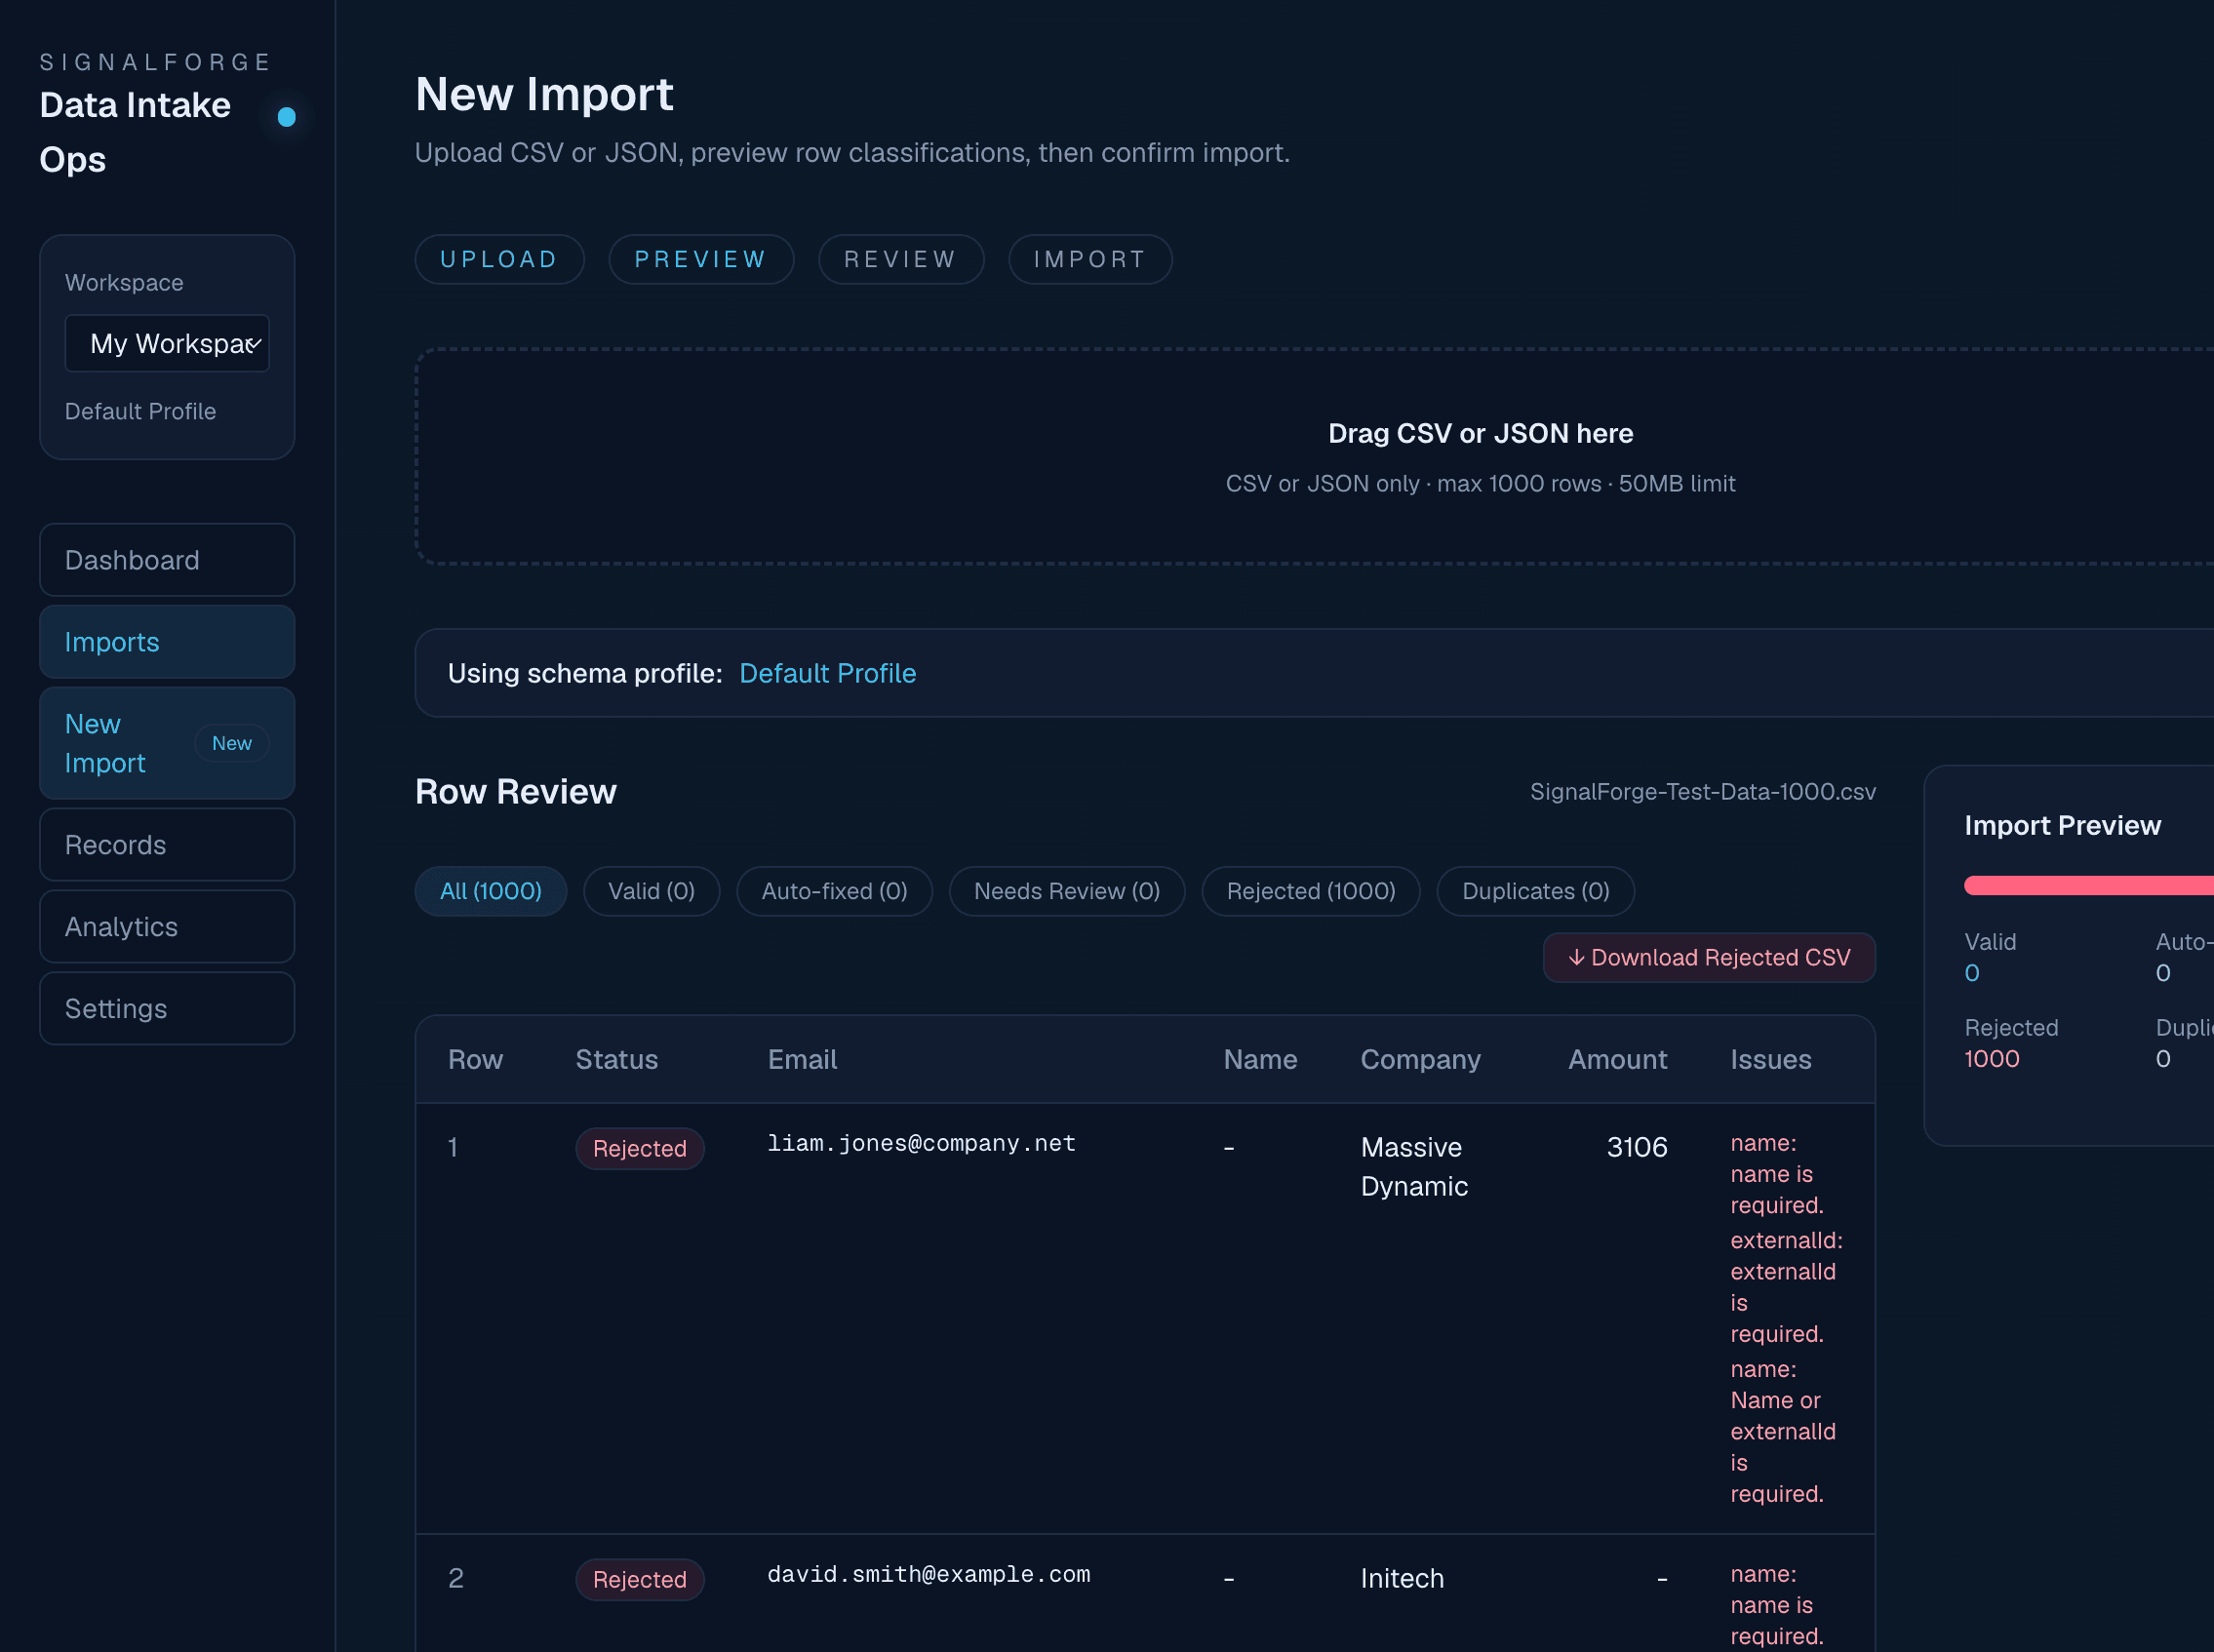
A production-grade data intake platform. Drag-and-drop CSV/JSON upload, row-level validation against configurable Zod schemas, intelligent preprocessing (currency coercion, email normalization, string trimming), configurable deduplication, import preview with auto-fixed / needs-review / rejected / duplicate row classification, a durable audit trail preserving original and cleaned state, schema profile management, an analytics dashboard with quality metrics, and team workspaces with RBAC.
Problem
What it solves.
Teams that ingest data from external sources spend hours cleaning CSVs, debugging validation errors, and tracking down duplicates. SignalForge turns that into a repeatable pipeline: upload, validate, preview, and commit — with full audit visibility.
What I built
The specific parts I implemented.
What I owned
My responsibility surface.
Product direction
Backend architecture & data model
Validation engine & deduplication logic
Full-stack implementation
Test + verification strategy
Architecture
How data moves through the system.
Screenshots
What the system looks like.
Data model
What entities the system tracks.
- id
- profile_id
- file_name
- row_count
- status
- created_by
- created_at
- id
- import_id
- data
- cleaned_data
- status
- errors
- duplicate_of
- id
- name
- rules
- transformations
- duplicate_keys
- id
- import_id
- row_id
- action
- actor
- diff
- created_at
Failure handling
What happens when something breaks.
Malformed CSV or unparseable file
Dropzone rejects with a descriptive error; no partial writes to the database.
Row fails Zod validation
Row marked as rejected with per-field error details; import continues with remaining rows.
Duplicate row detected
Row classified as duplicate and linked to the original via duplicate_of; not committed as a new record.
Preprocessing coercion fails
Row moved to needs_review instead of silently dropping or corrupting data.
Verification
How I tested or evaluated it.
- ✓npm run test runs Vitest suite covering parser, normalizer, cleaner, validators, and dedupe.
- ✓npm run build compiles without errors (Next.js 16 + TypeScript strict).
- ✓npm run lint passes with zero warnings.
- ✓Manual QA path documented in README: upload messy CSV, verify row classification, confirm commit preserves only valid rows.
- ✓Seed script produces baseline data for manual inspection.
Eval harness
Cases, expected, actual.
Clean CSV imports without errors
pass- Input
- Upload a well-formed CSV with 10 rows matching the active schema profile.
- Expected
- All 10 rows classified as valid and committed.
- Actual
- 10/10 rows passed validation; import completed with 0 rejected, 0 needs-review.
Messy data is coerced or flagged
pass- Input
- Upload CSV with mixed-format amounts ($1,200, 1200, '1,200.50'), inconsistent casing (USER@EXAMPLE.COM), and extra whitespace.
- Expected
- Rows with coercible values are auto-fixed; uncoercible rows move to needs-review.
- Actual
- 8/10 rows auto-fixed (currency coerced, emails lowered, whitespace trimmed); 2 flagged needs-review for ambiguous values.
Duplicate rows detected at import time
pass- Input
- Upload CSV where 3 rows are duplicates of previously committed records (matched on configured keys).
- Expected
- Duplicates classified and excluded from commit.
- Actual
- 3 rows marked duplicate, linked to originals; 7 new rows committed.
Next improvements
Known gaps & next moves.
- →JSON Lines and Excel (.xlsx) import support.
- →Scheduled / recurring import jobs (cron-triggered from S3 or webhooks).
- →Multi-tenant data isolation with row-level security.
- →Export pipeline for cleaned records (CSV, JSON, API endpoint).
- →Webhook notifications on import completion (Slack, email).